
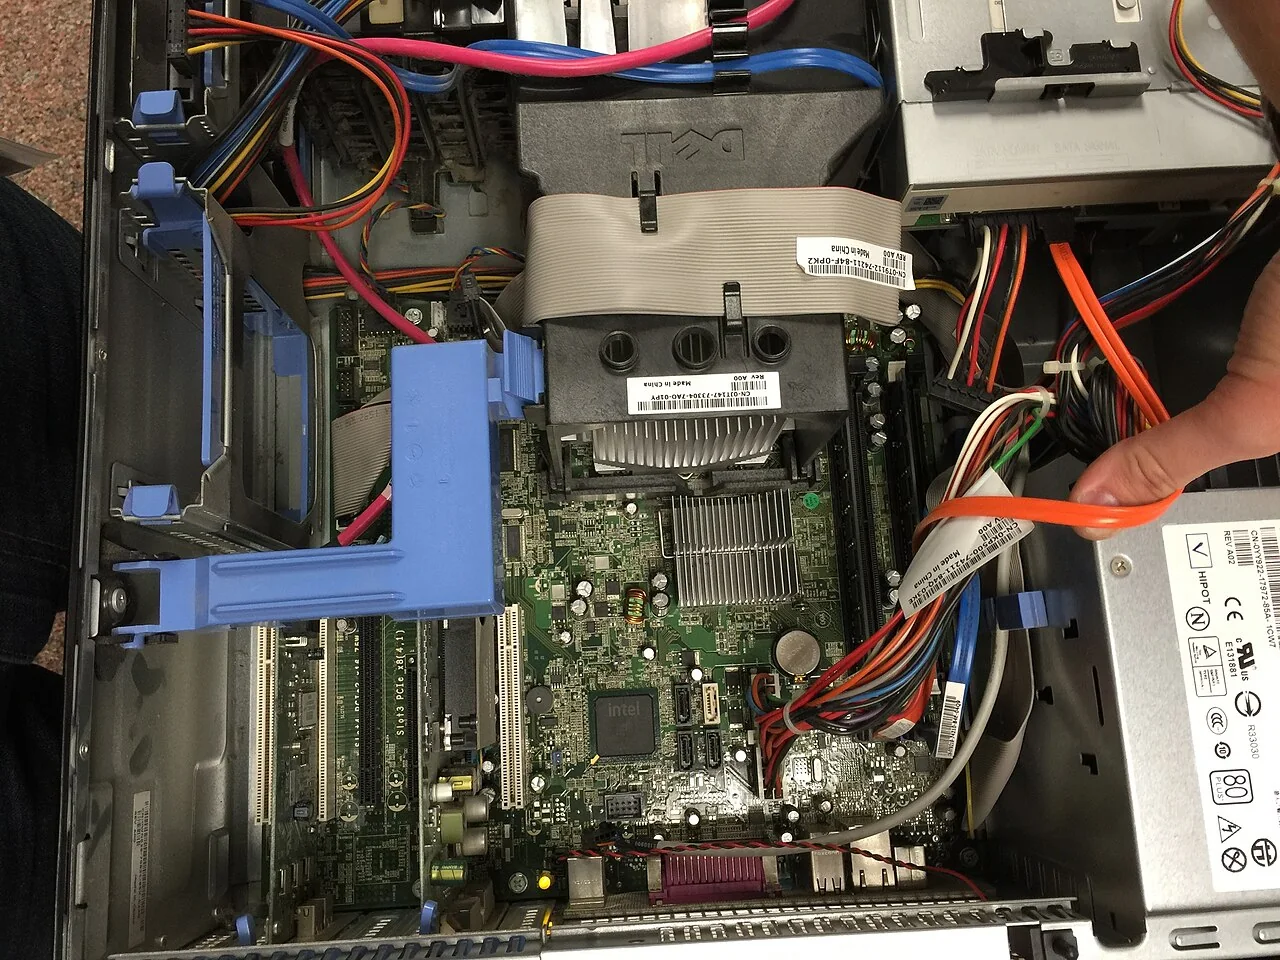
Running a model on your own computer sounds like a one-time installation. In practice, it is closer to maintaining a small piece of infrastructure. The decision should not begin with a model ranking or a graphics-card recommendation. It should begin with a repeated task, a clear reason that the task belongs on your device, and a realistic account of the time required to keep the system working. Three costs matter most: the cost of sufficient hardware, the cost of operating and maintaining the setup, and the cost of any task-quality compromise imposed by the chosen model and hardware. A local model is not inherently less capable than a hosted one; compare the actual configurations on the same work.
The problem: local does not mean free
A cloud service bundles inference hardware, updates, availability, and troubleshooting into a subscription or usage fee. A local setup separates those costs and makes many of them less visible. Storage is consumed by model files and multiple quantized variants. Electricity use increases during long inference sessions. Drivers, runtimes, and model launchers occasionally break after updates. The hours spent diagnosing those problems have a value even when no invoice arrives.
There is also a difference between a model that loads and a model that supports useful work. Hugging Face documents that the key-value (KV) cache can become a memory bottleneck for long-context generation. Its quantization guidance describes storing weights at lower precision to reduce memory requirements while trying to preserve accuracy. Neither statement predicts a particular speed or error rate for your device. Record the model revision, precision, runtime, input length and output checks together. Quantization benefits and task quality must be evaluated for that configuration; this article reports no hardware benchmark. Published benchmark numbers rarely include your document format, prompt, language mix, or tolerance for delay. For that reason, hardware should be evaluated against a test set rather than against an abstract claim that a device is “AI ready.”
Where local models make sense
Local inference is most compelling when the task is frequent, the input should not be sent to a general third-party service, and the current device already reaches an acceptable speed. Useful examples include tagging a private research archive, drafting fixed-format notes from internal documents, transcribing recordings in an offline location, or building a read-only search layer over material that cannot be placed in a consumer account. In each case, the work repeats often enough to justify setup and testing.
Local is usually less attractive for occasional general questions, live web research, seamless cross-device use, or work that needs the strongest available multimodal model. It is also wrong to equate local with automatically secure. Disk encryption, operating-system accounts, model-source integrity, backups, and physical access still matter. If several people use the same machine, a locally stored prompt history may expose more information than a well-administered enterprise service would. The correct comparison is between complete operating models, not between the words “cloud” and “local.”
Applied workflow: classifying interview transcripts
For a recurring interview-classification task, begin with transcripts that have already been coded by a qualified person and remove identifiers not needed for the test. Give each candidate model the same label definitions and output format. Record whether it follows the taxonomy, misses negation, invents themes, quotes the right passage, and completes the job within the allowed time. A fluent summary receives no credit if its evidence cannot be located in the transcript.
After selecting a model, freeze the model version, quantization, prompt, and runtime settings. Let the model propose themes and supporting passages while a person remains responsible for interpreting what a participant meant. Send a defined sample for second review, and add recurring errors to the test set. This workflow turns a preference for privacy into a measurable process. It also exposes when the local model is not good enough, which is useful information before anyone buys a new computer.
A practical evaluation sequence
Start by writing down the weekly number of runs, typical input length, maximum acceptable wait, required output, and consequence of an error. Classify the input as public, internal, sensitive, or prohibited. Decide which categories may be processed by each available tool. Next, collect ten to twenty real examples, including awkward cases, long files, tables, and inputs containing negatives or dates. Run them on the hardware you already own before considering an upgrade.
Measure wall-clock time, memory use, output accuracy, and the amount of human correction. Keep failed examples; an average score can hide a dangerous pattern around numbers or exceptions. Estimate the annual cost of the local system by including hardware depreciation, extra storage, electricity, and maintenance time. Compare that number with a suitable hosted plan and with the option of doing the task manually. Finally, document how to update or roll back the model, where files are stored, and who reviews output. A setup that only one enthusiastic person can repair is a fragile production system.
Risks, limits, and a testable conclusion
Local processing removes one path by which data could leave the device, but it does not remove software-supply-chain risk, malicious model files, excessive permissions, theft, or accidental backups to a consumer cloud folder. Generated output can still be false, biased, or overly confident. Licensing terms may restrict how a model or its output can be used. A local retrieval system can also reveal passages to people who were never authorized to read the underlying documents.
Approve a local workflow after evaluating task frequency, input sensitivity, measured performance and who can maintain it. If one of those conditions is absent, begin with a smaller pilot rather than a hardware purchase. Re-run the same test set after every material model or runtime update.
Compare two configurations without inventing a benchmark
Fill this record after running an approved task. Blank results mean not measured; a model that loads has not yet passed a quality or cost comparison.
| Field | Local configuration | Hosted alternative |
|---|---|---|
| Identity | Model revision, precision, runtime, device | Service, plan, model identifier, review date |
| Workload | Same approved input and expected output | Same task and authorized input category |
| Observed performance | Elapsed time, peak memory, failures: not measured | Elapsed time, output failures: not measured |
| Human effort | Setup + maintenance + output checking hours | Administration + output checking hours |
| Annual cash estimate | Allocated hardware cost + storage + electricity | Plan or measured usage charges |
| Decision | Accept only if required outputs and recovery work | Do not assume a subscription removes review costs |
Select or copy plain text
Field	Local configuration	Hosted alternative
Identity	Model revision, precision, runtime, device	Service, plan, model identifier, review date
Workload	Same approved input and expected output	Same task and authorized input category
Observed performance	Elapsed time, peak memory, failures: not measured	Elapsed time, output failures: not measured
Human effort	Setup + maintenance + output checking hours	Administration + output checking hours
Annual cash estimate	Allocated hardware cost + storage + electricity	Plan or measured usage charges
Decision	Accept only if required outputs and recovery work	Do not assume a subscription removes review costs
Copy a blank comparison record
Task:
Approved input category:
Configuration A / version:
Configuration B / version:
Expected output and critical failures:
Observed runtime / memory / corrections: NOT MEASURED
Annual cash inputs and assumptions:
Maintenance and review hours:
Decision / reviewer / date:
Select or copy plain text
Task:
Approved input category:
Configuration A / version:
Configuration B / version:
Expected output and critical failures:
Observed runtime / memory / corrections: NOT MEASURED
Annual cash inputs and assumptions:
Maintenance and review hours:
Decision / reviewer / date:
REFERENCES
Sources and further reading
- 01NIST Generative AI Profile (AI 600-1, July 2024)
- 02OWASP Top 10 for Large Language Model Applications
- 03Hugging Face Transformers: Quantization overview
- 04Hugging Face Transformers: KV cache strategies
Sources reviewed October 20, 2026. Provider instructions and product terms can change. Examples identified as fictional are editorial illustrations, not reported events or product tests.